
Technical Overview
Serverless GPU Compute in the Cloud | ML Team Comparison
by Chuan Qiu
A practical framework for choosing between SDK-first, container-first, and environment-first serverless GPU platforms for ML workloads.
2026-04-02
5 min read
Stay ahead of the curve in cloud development. Get the latest insights, tutorials, and product updates about cloud infrastructure, AI development, and the Velda platform.
A practical framework for choosing between SDK-first, container-first, and environment-first serverless GPU platforms for ML workloads.
Optimize Dockerfile ordering, shrink images, tune target machines, defer installs, and try development container streaming to cut iteration times from minutes to seconds.
Why decorator-heavy Python orchestrators introduce hidden operational costs, and how CLI-first tooling restores reproducibility and simplicity.
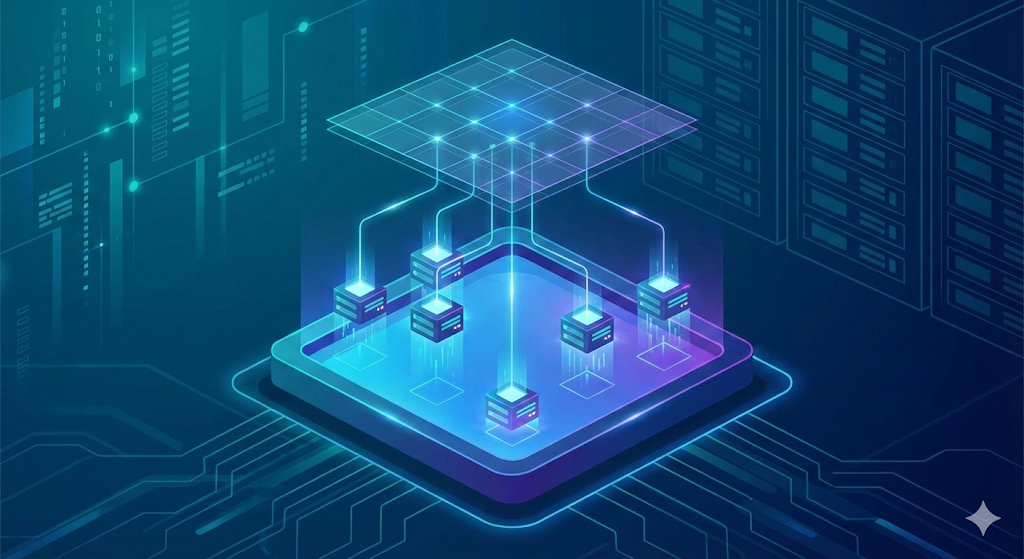
A Velda pool manages worker lifecycle (create, verify, retire) so `vrun` can scale compute across clouds, Kubernetes, and data centers without manual VM provisioning.
Guide to run vLLM on SLURM clusters: create batch scripts, submit jobs, access endpoints, and follow best practices for reliable HPC inference.
Velda replaces OCI images with a remotely mounted root filesystem and demand-driven file fetching, prioritizing rapid iteration for ML development.

Learn how to run Jupyter Notebooks on HPC clusters using SLURM with SSH tunneling, or discover how Velda simplifies the entire process to a single command for seamless interactive data science workflows.

How Kumo.ai used Velda to accelerate experiments, cut dependency update times, and increase GPU utilization across the team.

Build sophisticated ML workflows with Velda's simple commands. Learn to create pipelines with dependencies, parallel processing, and fan-out patterns for scalable machine learning.

Why vrun is the ultimate solution for AI/ML researchers struggling with inefficient GPU setups. Learn how one command can provide instant scaling, cost efficiency, and seamless development experience.

AI/ML researchers are stuck with inefficient GPU setups that limit productivity and increase costs. Learn how Velda provides instant access to scalable compute without the complexity.
AI developers face a painful dilemma: deal with container complexity or pay thousands for idle instances. Velda offers a better way - instant access to any compute configuration with simple commands.